You've got the call from a client, or maybe you're cleaning up your own site. The old WordPress pages are supposed to be gone, the redesign is live, and yet Google still shows the stale URL, the old title, or a cached snippet that shouldn't exist anymore. That's the moment you realize removing a website from Google search isn't one action, it's a sequence, and if you skip the site-side fix, the page tends to come back.
Why Getting a Site Out of Google Feels Harder Than It Should
A designer usually runs into this after a launch is already late, a client wants the old brand buried, and search results still keep surfacing the wrong pages. The problem starts when temporary hiding gets treated like permanent removal. Google separates those jobs clearly, and that gap is where most failed removals begin.
Temporary block is not deindexing
The Removals tool in Search Console can hide a result quickly, but Google treats that block as temporary. If the page stays live and crawlable, Google can bring it back after recrawling, which is why people see “ghost” pages return after they thought the job was finished, as described in the Google removal workflow. A removal request by itself does not close the loop.
The practical rule is simple. Use Search Console to buy time, then make the page impossible, or at least unnecessary, for Google to keep in its index. Google says a URL removed with the tool is blocked for about six months before it can reappear unless you make a permanent change on the site itself, as covered in the Google Removals tool guidance.
Practical rule: if the page still returns usable content, Google has a reason to keep it.
URL removal and full domain cleanup are different
A single URL disappearing from results is not the same as a whole site being deindexed. Sometimes the problem is one stubborn landing page, sometimes it is an entire staging site, duplicate theme archive, or old subdirectory. The fix changes depending on which of those you are dealing with.
If you own the content, Google wants the site to change first, then the search result to follow. That order matters because Search Console only gives you a temporary block, while the site itself has to do the permanent work through deletion, updating, password protection, or noindexing.
Permanent Removal Methods You Control on the Site
A removal request only buys time if the page still behaves like a live page. For a permanent exit, Google gives you a short list of site-side signals: delete the content, return 404 (Not Found) or 410 (Gone), password-protect the page, or add a noindex directive so the URL can still load but stay out of search. Anything outside that list is usually a workaround rather than a clean exit.
Choose the signal that matches the situation
A 404 tells Google the page is missing. A 410 is stronger because it says the page was intentionally removed. Both can work, but a deliberate takedown is usually clearer with 410, because it leaves less room for interpretation.
A noindex tag or X-Robots-Tag header fits pages that should remain available to users but stay out of search results. The catch is simple, Google has to crawl the page to see that directive, so robots.txt alone will not reliably remove it from the index. That mistake still catches a lot of site owners, especially when they block a URL too early and never let Google read the index control.
If Google can't crawl the page, it can't read the noindex directive.
Password protection makes sense when the page should exist, but only for approved viewers. I use that path for client portals, internal drafts, and prelaunch work where public access is the problem. Deleting the content is the bluntest option, but it is also the cleanest choice when there is no reason to keep the page live.
Permanent removal methods compared
| Method | Signal Type | Best For | Watch Out For |
|---|---|---|---|
| Delete the content | Content removal | Pages that should no longer exist | Leaving internal links or sitemap entries behind |
| 404 Not Found | Missing page | Accidental or retired URLs | Soft 404 pages that still look real |
| 410 Gone | Explicit removal | Deliberate takedowns | Returning the page later without changing strategy |
| Password protection | Access restriction | Private or internal content | Accidentally leaving public previews open |
| noindex tag or header | Indexing control | Pages that should stay live but not rank | Blocking crawling before Google can read the directive |
The trade-off is speed versus certainty. Search Console can hide the result quickly, but the site-side change is what keeps it from resurfacing after recrawl. That is the part many guides skip, and it is why a page disappears for a while, then shows up again as if nothing happened, as noted in the Google Removals tool guidance.
Using Search Console's Removals Tool the Right Way
A removal request in Google Search Console is useful when a client needs a result hidden fast while the site-side cleanup is still in progress. It belongs in the workflow, but it does not replace the actual fix on the site. Google treats the block as temporary, so the URL can come back if the live page still exists in a crawlable state, as noted in the Google removal workflow.
Start with the exact URL you want suppressed. Use the full canonical form, not a rough match, and only submit other variants if each one is a real, separate URL. The tool gives you two request types, temporarily remove URL and clear cached URL. The first hides the result from search, while the second removes the cached snapshot for the request period.
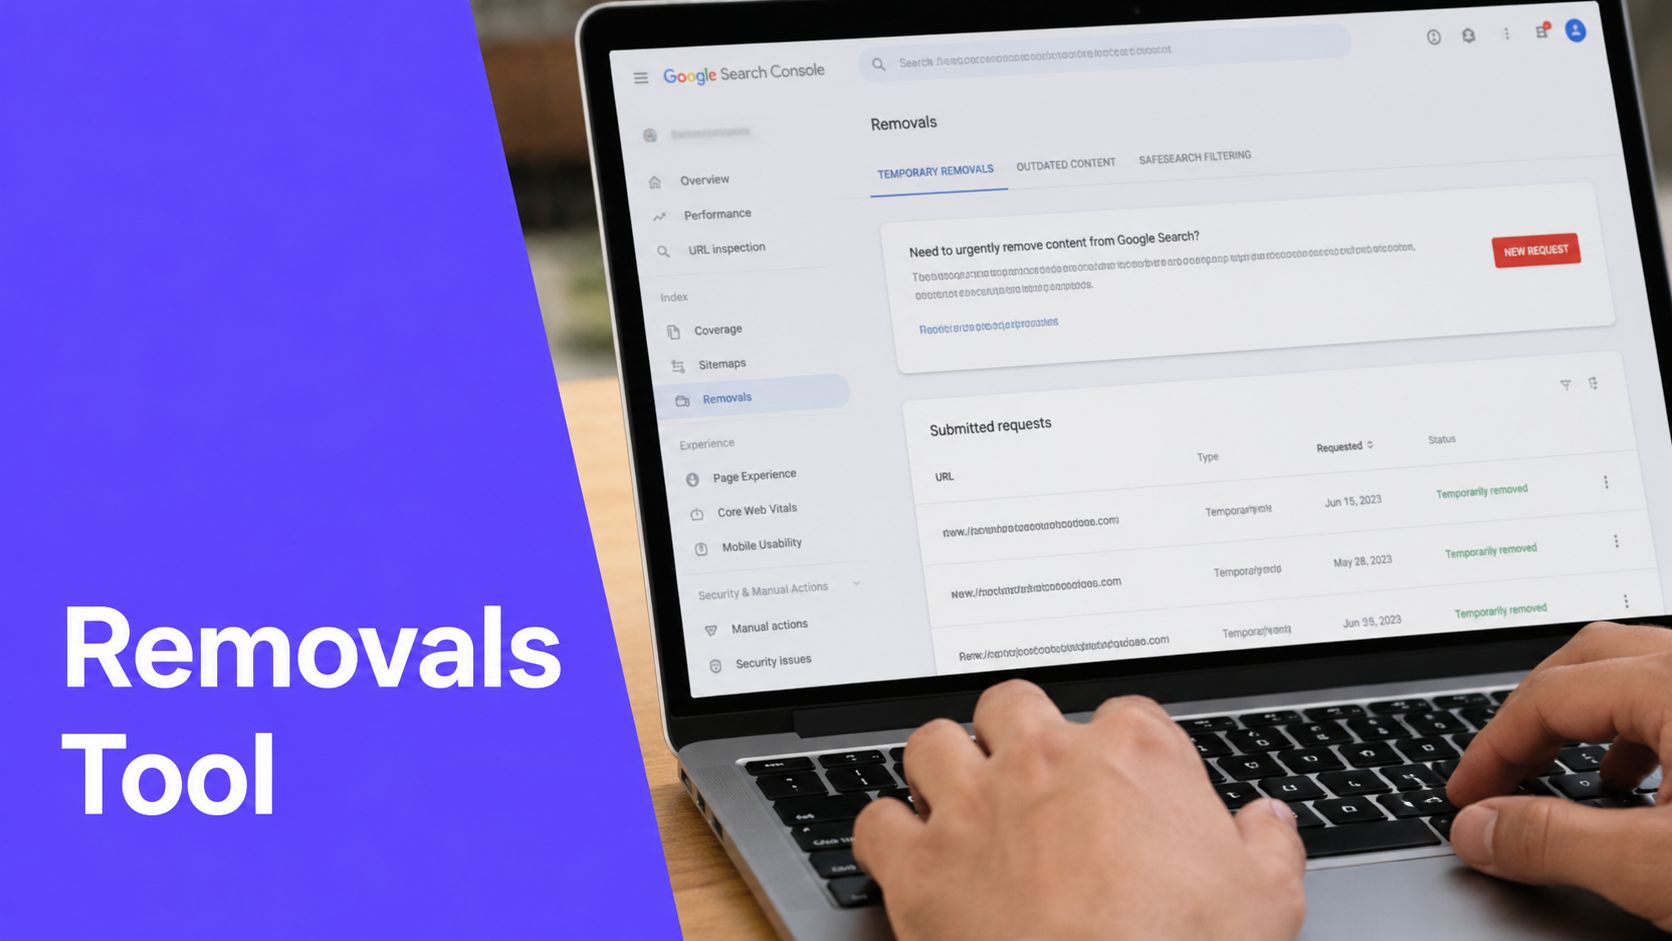
The sequence matters. Make the site-side change first, then open Search Console, choose the right request, paste the exact URL, and submit it. If the page still loads publicly and Google can still crawl it, the request only buys time. The URL may reappear at the next recrawl if the underlying issue was never fixed.
Which request to choose
Use temporarily remove URL when the result needs to disappear from search quickly. Use the cached copy option when the live page has been corrected but you still want the old snapshot hidden. If the page stays live and should never rank, noindex is usually the better fit than a removal request.
A page that is gone is better handled with 404 or 410. A page that still serves users but should stay out of the index belongs behind noindex. A private page belongs behind password protection. Search Console supports the permanent fix rather than replacing it.
The limit matters. Google says a URL removed with the tool is blocked for about six months before it can return unless the site itself has been fixed permanently, as covered in the Google Removals tool guidance. I treat the tool as a short-term pressure release, not the repair itself.
WordPress and Elementor Implementation Paths
On WordPress, the cleanest removals usually happen without touching theme files. That saves time, because the fix often lives in the page settings or the SEO plugin, not inside templates. In Elementor builds, the task gets easier once you know where the indexing controls sit and which output reaches Google.
Use the SEO plugin for page-level control
Rank Math, Yoast, and AIOSEO all let you set page-level noindex without editing code. That matters because the directive needs to appear in the rendered HTML, and the plugin is usually the safest place to put it. If a page should stay public for users but disappear from Google, this is the most common path.
For WordPress removals, I usually check three places in this order. First, the page's own SEO settings. Second, the template or archive settings if the content is generated dynamically. Third, the sitemap output, because a URL left in the sitemap keeps advertising itself to crawlers even after the visible page changes. I also look at whether the page is still linked from menus, related posts blocks, or Elementor widgets, since those internal paths can keep the URL alive longer than the editor suggests.
Elementor and Exclusive Addons builds need a rendered HTML check
Elementor makes it easy to design the page and just as easy to miss the indexing setting. If you're using a plugin panel in the page editor, confirm that the final HTML contains the robots meta tag or header directive. Don't assume the visual editor saved it correctly. Open the page source, inspect the rendered output, and verify the directive is there.
If the site uses saved templates in an addon library, watch for orphaned content. A deleted page can still leave behind reusable sections, headers, footers, or template parts that remain publicly reachable through another URL. That hidden duplicate often explains why a page seems removed in the editor but still shows up in Google. I've seen this most often in Elementor setups with shared sections, especially where Exclusive Addons or similar libraries are used to reuse blocks across multiple pages.
A removal attempt fails fastest when the page is gone in the editor but still published through a template, archive, or duplicate URL.
Don't confuse crawling control with indexing control
Robots.txt controls crawling access rather than indexing decisions. It can keep Google from fetching a page, but it does not reliably tell Google to remove a page it already knows about. If the goal is removal, robots.txt is only a supporting measure, and only after the page is already handled by a stronger signal.
In Elementor projects, I've seen the best results when the team uses the SEO plugin for noindex, removes the page from the menu and sitemap, and then submits the temporary removal in Search Console. That sequence gives Google a clear story. The page is no longer meant to exist in search, and the site confirms it.
Handling Mirrored, Cached, and Republished Content Elsewhere
The hardest removals are usually the copies you do not control. I have had clients delete a page from WordPress, clear it from the sitemap, and still find the same text ranking because an aggregator, scraper, or old mirror kept republishing it. Google will usually expect you to start with the site that is hosting the copy, as noted in the Google's mirrored content guidance.
Start with the host, not with Google
If you do not control the mirror, contact the host and ask for removal or noindex. Keep the request short and exact. Send the live URL, explain that the content is an unauthorized duplicate, and ask for a specific action, not a generic reply.
A practical example is a content aggregator that republishes your article at a new URL while keeping the headline, body copy, and images intact. In that situation, Google is seeing two pages, and the duplicate can keep showing even after your original page is gone. I have seen this happen with scraped WordPress posts that were copied into network sites, old syndication feeds, and low-quality “news” mirrors.
Before you contact the host, document the problem. Save the source URL, the mirror URL, screenshots of the duplicated content, and the date you checked it. If the site is running on WordPress, note whether the copy appears in a page, a post, an archive, or an Elementor template because that helps the host find it faster. If the mirror uses SEO plugins, that detail can also matter, since a noindex setting in Rank Math, Yoast SEO, or another plugin may be easier for the host to apply than a full page removal.
If the copy is a legal issue, a copyright removal request or another legal process may be the better route. If it is only an unwanted duplicate, direct contact is usually faster than escalating first. Google can help with search visibility, but it cannot permanently remove a page that still exists on another host.
Caches and archives are separate headaches
A page can disappear from the live web and still stay visible in cached or archived systems for a while. That is why cleanup often has two parts, the source copy and the search-visible copy. Once the host returns 404 or 410, Google usually stops treating the page as live and then clears its cached version after recrawling, but that only works if the source is gone.
Archive services are a different case. If the page has been captured elsewhere, you need to deal with that host directly or use whatever removal process that service accepts. Search Console removal tools do not erase every copy across the web, and clients often miss that distinction the first time they try to clean up a site.
If the content belongs to you and the mirror is not authorized, keep your evidence organized before you request anything. Save the URLs, screenshots, timestamps, and any response from the host. If the takedown path turns into a legal matter later, that record makes the next step much easier.
Verifying Removal and Troubleshooting Reappearances
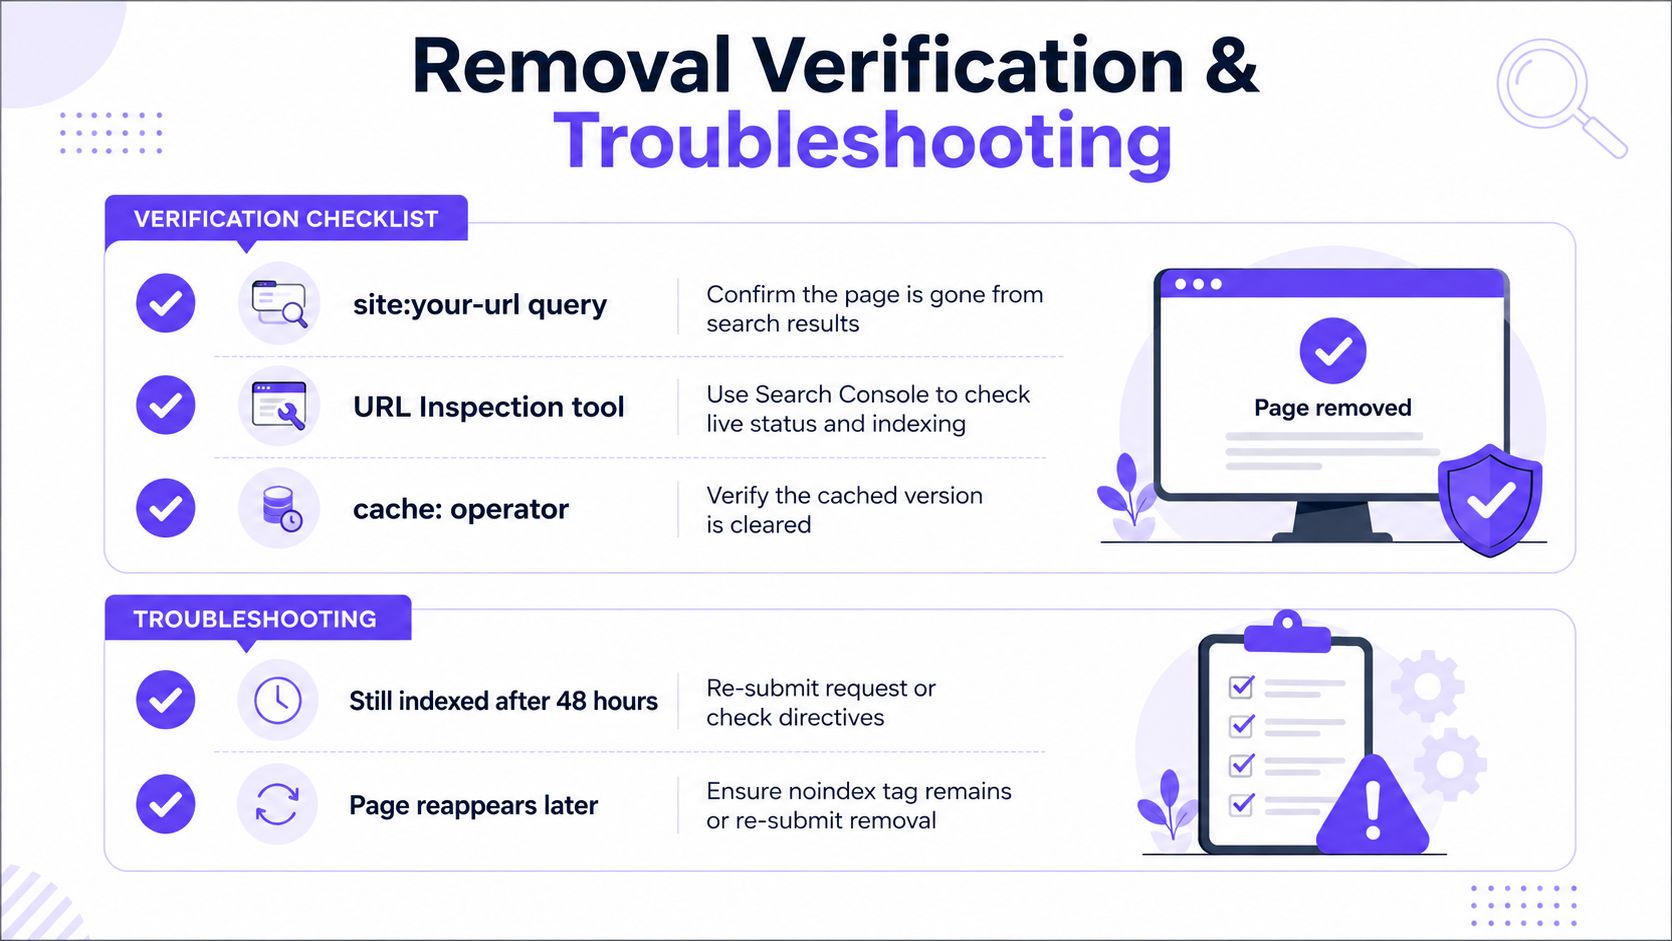
The quickest way to confirm a removal is to check what Google still shows, then verify the live page at the source. A site: query tells you whether the URL is still indexed, the URL Inspection tool in Search Console shows what Google can fetch from the live page, and the cache: operator can reveal whether an older copy is still hanging around. Used together, those checks give you a clear read instead of guesswork.
Reappearance usually means one of a few things
The most common problem is a page that still returns 200 OK after the team assumed it was gone. Google sees a live, crawlable URL and has a reason to keep it in play. The fix is a real 404, a real 410, or a working noindex directive, not a visual redesign that only looks removed.
A second issue is the soft 404. The page looks empty or deleted to a person, but the server still serves a normal page response. That creates mixed signals and often slows down cleanup. The server response has to match the content, not just the layout.
A third issue is a canonical conflict. I see this often on WordPress builds where the page is removed, but another version of the URL still points Google somewhere else through a conflicting canonical tag. If the canonical tag points to a live page, Google may keep treating the removed URL as related to something active.
Check the obvious culprits first
- Internal links still point to the page: Remove menu links, footer links, and related-post links so you are not signaling that the page still matters.
- The URL remains in a sitemap: Remove it from the sitemap source so crawlers stop treating it like an active target.
- The noindex tag is not rendered: Check the final HTML, not just the WordPress editor or the page builder preview.
- Robots.txt blocks crawling before Google can read noindex: Remove the crawl block if you need Google to see the directive.
- A mirrored copy still exists elsewhere: Contact the host or use the relevant legal removal route if the copy cannot be resolved informally.
- The canonical tag points somewhere unexpected: Make sure the removed URL is not canonicalized to a different live page, or you can end up with the wrong page being treated as the preferred version.
If the page comes back after a temporary block, check whether the site-side fix is still in place. Google's workflow depends on the temporary suppression and the permanent change on the website both being aligned, so a removal request by itself will not hold if the content stays live, as noted earlier.
Key Takeaways for a Clean Exit
A clean removal depends on the sequence, not just the tool. Get the page off the site first with the permanent method that fits the situation, then use Search Console for temporary suppression if you need a fast stopgap, and expect noindex changes to take effect only after Google recrawls the URL. In practice, that usually means a wait of a few weeks before the clean state becomes visible everywhere, especially on WordPress sites with cached templates, reused blocks, or multiple hosts serving similar paths.
The hard part is usually the same in client work. A page comes back because one host still serves it, a canonical still points Google at a live version, or the removal request was treated as a pause instead of a fix. Temporary removal and permanent removal do different jobs. If the site-side change is missing, the URL can reappear later even after it looked gone in Search Console, as noted earlier.
For WordPress and Elementor builds, verify the final HTML, not the editor view, and check the page source in the live rendered output. SEO plugins can add the right directive, but only if the page settings, template output, and caching layers all agree. In Elementor-heavy builds, I also check whether Exclusive Addons widgets or saved templates are reusing a removed page structure somewhere else on the site, because that kind of reuse can keep signals alive longer than people expect.
Mirrored and republished copies need their own cleanup. Google will not treat a stale copy on another host as solved just because the original page is gone, so direct outreach, takedown requests, or the appropriate legal route still matter when the content is outside your control (Google mirrored content guidance). For bulk checks, a simple URL list is often faster than clicking one page at a time, especially when you are confirming the same pattern across an old domain, a staging host, and a CDN-backed subdomain.
The clean exit is simple to describe and easy to miss in execution. Remove the page, clear the conflicting signals, confirm the fix in Google's own tools, and keep one eye on the other hosts that might still be serving the same content. If you skip any of those steps, the URL usually returns later in a different form.